Post Date: October 6, 2018
Last Updated: September 27, 2026
Introduction
This guide explains how to install and use the AWS Command Line Interface (AWS CLI) to access and manage an S3 bucket — uploading, downloading, syncing, and managing objects directly from the terminal.
One important update from the original version of this guide: it installed AWS CLI v1 via pip. AWS now recommends AWS CLI v2 — a self-contained installer that doesn’t depend on Python at all, receives ongoing feature updates, and is the version AWS documents by default going forward. The steps below use the current v2 installation method.
Prerequisites
- A Linux, macOS, or Windows machine with terminal access
- An AWS account with an IAM user (or role) that has S3 permissions
- That user’s Access Key ID and Secret Access Key
Architecture
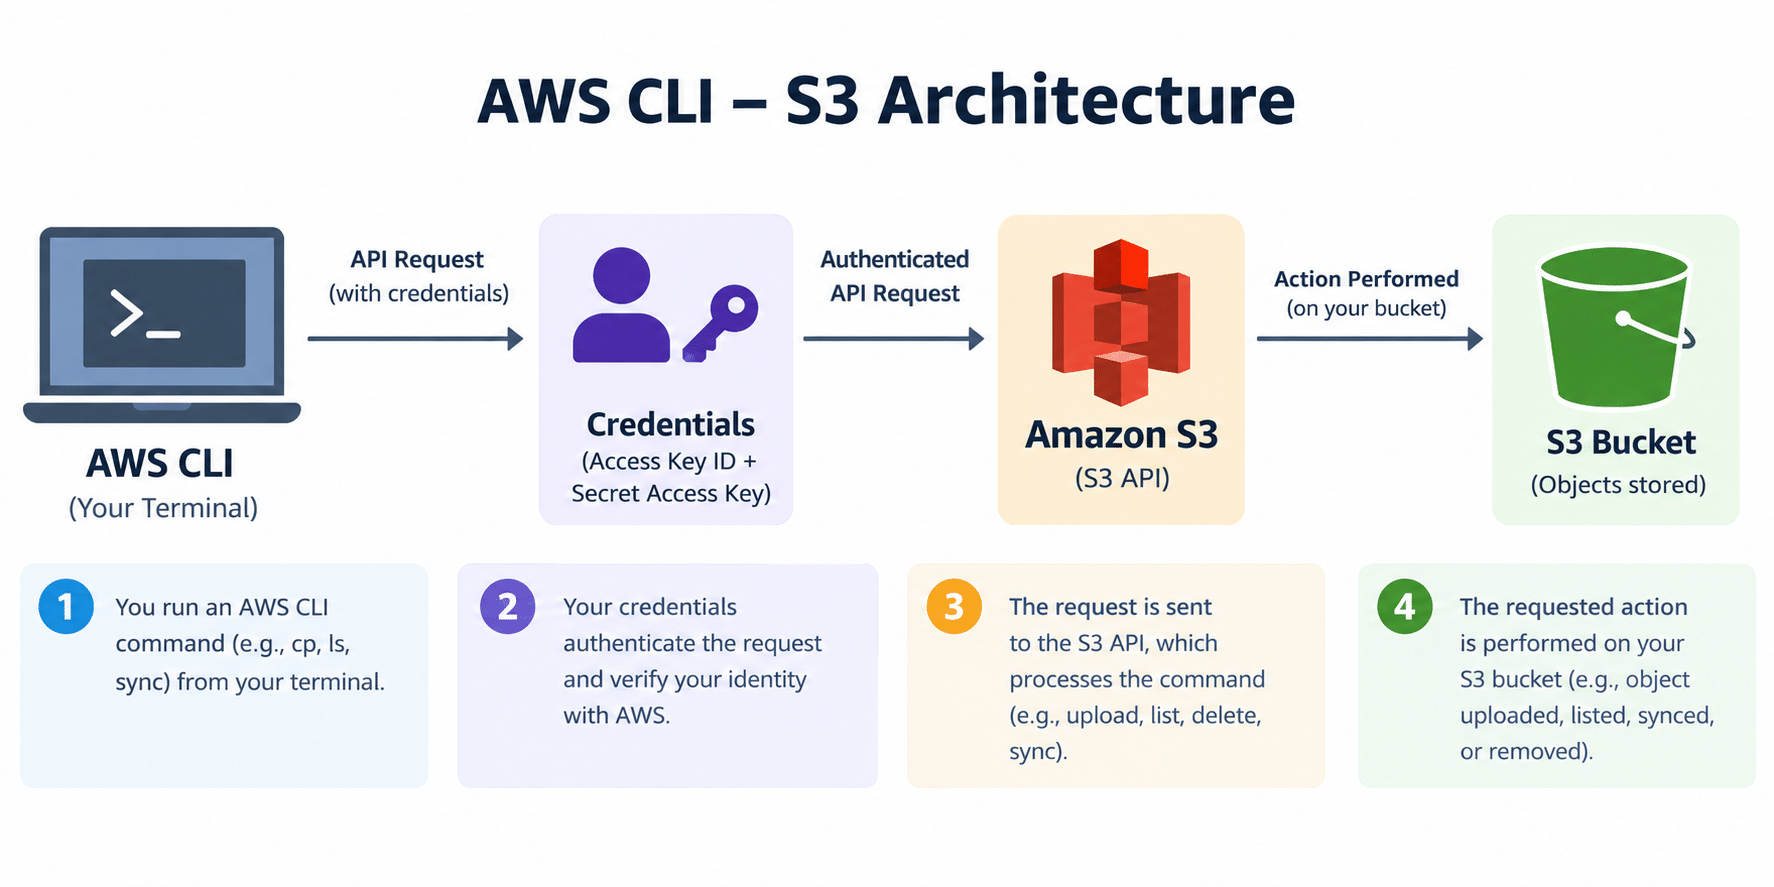
- The AWS CLI is a client — it doesn’t store anything itself, it just sends authenticated API requests to AWS
- Your credentials (Access Key ID + Secret Access Key) authenticate every request
- Each command maps to an underlying S3 API call —
aws s3 cpuploads/downloads objects,aws s3 lslists them,aws s3 syncreconciles a local folder and a bucket
Steps
1. Install AWS CLI v2
Linux:
curl "https://awscli.amazonaws.com/awscli-exe-linux-x86_64.zip" -o "awscliv2.zip"
unzip awscliv2.zip
sudo ./aws/install
macOS:
curl "https://awscli.amazonaws.com/AWSCLIV2.pkg" -o "AWSCLIV2.pkg"
sudo installer -pkg AWSCLIV2.pkg -target /
Note: The original guide installed AWS CLI v1 via Python and
pip(curl get-pip.py, thenpip install awscli). That method still technically works, but AWS CLI v2 is now the recommended version — it’s a standalone installer with no Python dependency, and gets ongoing feature updates that v1 generally doesn’t.
2. Verify the Installation
aws --version
You should see output confirming an aws-cli/2.x version.
3. Configure Your Credentials
aws configure
AWS Access Key ID [None]: <your access key>
AWS Secret Access Key [None]: <your secret key>
Default region name [None]: us-east-2
Default output format [None]: json
Security note: Never share or commit these keys anywhere public. If you’re working on a shared or long-lived server, consider using an IAM role instead of static keys where possible.
4. Create a Bucket
aws s3 mb s3://your-bucket-name
5. Upload a File to the Bucket
aws s3 cp ./tests.txt s3://your-bucket-name/folder/
6. List Your Buckets
aws s3 ls
7. Remove a Bucket
aws s3 rb s3://your-bucket-name
If the bucket name doesn’t match exactly, you’ll get a
NoSuchBucketerror — double-check the name against youraws s3 lsoutput first.
8. Sync a Local Folder with a Bucket
aws s3 sync ./local-folder s3://your-bucket-name
sync reconciles the contents of a local folder and a bucket (or two buckets), only transferring files that have actually changed — more efficient than re-uploading everything with cp each time.
9. Grant Specific Permissions on Upload (Optional)
cp, mv, and sync support a --grants option to set permissions on objects as they’re uploaded:
aws s3 cp ./file.txt s3://your-bucket-name/ --grants read=uri=http://acs.amazonaws.com/groups/global/AllUsers
| Field | Options |
|---|---|
| Permission | read, readacl, writeacl, full |
| Grantee_Type | uri, emailaddress, id |
| Grantee_ID | The actual URI, email, or canonical ID matching the type above |
Conclusion
Managing S3 from the command line comes down to installing AWS CLI v2 (rather than the older pip-based v1 method), configuring your credentials once, and using a small set of commands — cp, ls, rb, sync — that map directly to S3 operations. sync in particular is worth knowing well, since it avoids re-uploading unchanged files every time.
Frequently Asked Questions
Is AWS CLI v1 still usable? Yes, but AWS recommends v2 for new setups — it’s actively maintained with new features, while v1 is considered legacy.
Do I need Python installed for AWS CLI v2? No — that’s one of the main differences from v1. AWS CLI v2 is a self-contained installer with no Python dependency.
What’s the difference between cp and sync? cp copies a specific file or folder every time you run it, re-uploading everything. sync compares source and destination first and only transfers what’s actually changed, which is much faster for repeated backups.
Related Articles
How to Create an AWS S3 Bucket Using Terraform
How to Mount Wasabi Storage Bucket on CentOS and Ubuntu 20 using S3FS
Talk to Our Technology Experts
Managing cloud storage or building out your AWS infrastructure? Our team can help with cloud architecture, S3 automation, and ongoing AWS support.